Resilience Without the Tradeoff
Both sites carry live traffic at the same time. If one site fails, the other keeps running. No failover delay, no recovery window, no idle capacity sitting unused.
Scaling AI Across Sites: Inside the WhiteFiber Continuum Architecture
REGISTER NOW →
WhiteFiber Continuum™ is the fastest performing distributed GPU supercluster architecture.
Of Bandwidth
Of Guaranteed Latency
Across 83 Kilometers of Fiber
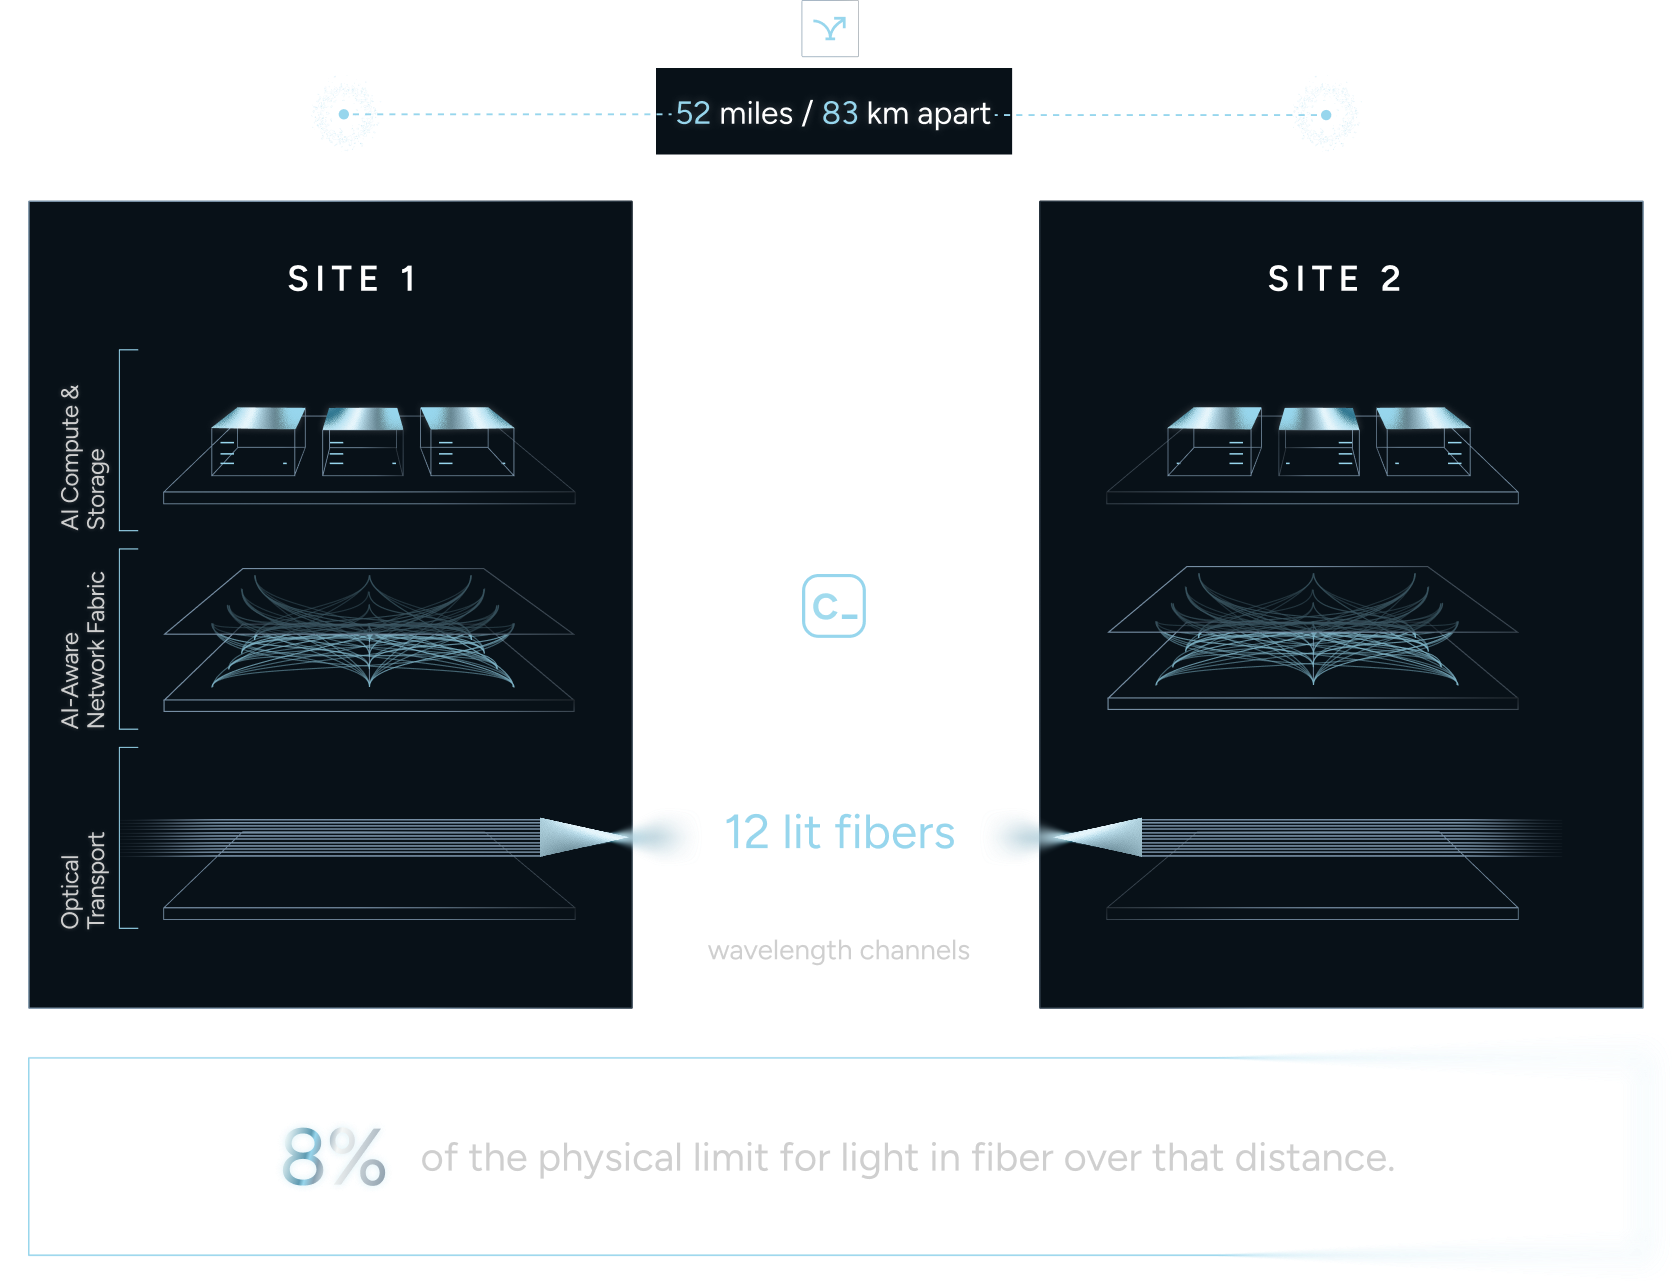
Both sites carry live traffic at the same time. If one site fails, the other keeps running. No failover delay, no recovery window, no idle capacity sitting unused.
Sensitive data never leaves the site where it originates. Only model gradients cross the inter-site link. Compliance is structural, not a policy layered on after.
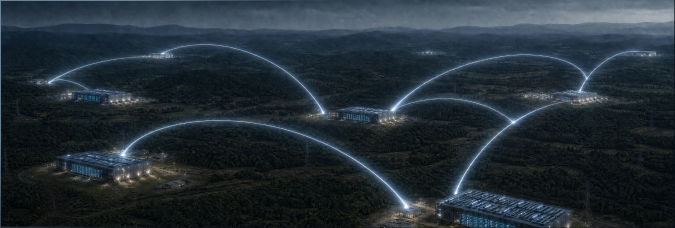
Run a single job across the full cluster, or split into independent workloads that burst across sites as demand shifts.
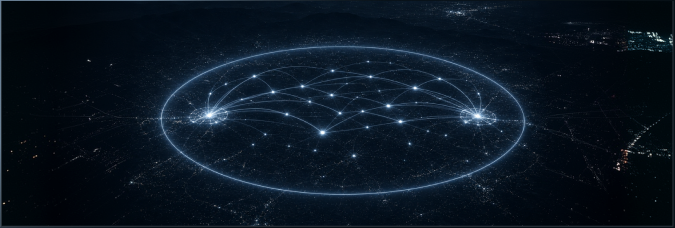
Additional sites join the same logical cluster as demand grows, using the same networking approach already in place. Nothing gets rebuilt.


We Removed it.
WhiteFiber Continuum links two data centers into a single logical GPU supercluster. It removes bandwidth as a constraint on how and where AI infrastructure gets deployed.


When your primary site runs out of power before it runs out of demand, WhiteFiber Continuum turns a second site into capacity instead of a separate project. Burst overflow training, ranking-model retrains, or any workload stuck waiting on an interconnection queue can run across both locations as one non-blocking cluster - not a bolt-on deployment your team has to manage independently. That means scaling past a single site's power ceiling without hiring a dedicated cross-site networking practice or accepting a performance cliff every time you add capacity.
Training runs that outgrow a single campus shouldn't have to wait years for a new one to be energized. WhiteFiber Continuum pools GPUs across two live sites into a single logical supercluster, so a multi-week pretraining or fine-tuning run keeps going - and keeps converging - even when it's split across locations. It's built for the workloads that actually stress a network: synchronized, bursty, loss-intolerant collective operations, not just generic east-west traffic. When a site-level failure would otherwise cost days of GPU-hours, Continuum's active-active fabric means the run continues on the surviving site instead of restarting from the last checkpoint.
Mission-critical AI workloads need compute that never leaves the country - and never depends on a single point of failure either. WhiteFiber Continuum joins two domestically-located, HITRUST-certified sites into one fabric, giving government and defense-adjacent organizations dual-site resiliency without ever routing data or workloads across a border. A single, converged network for compute, storage, and inter-site connectivity also means fewer separate systems to secure, document, and certify - a real advantage when every additional network boundary is another one to accredit.
Provable resiliency shouldn't come at the cost of provable compliance. WhiteFiber Continuum's two sites both carry live traffic simultaneously - if one fails, the other keeps running, with no manual failover and no idle standby capacity paying for itself. For financial institutions running quantitative research or life-sciences teams running computational drug discovery, that same active-active architecture protects long, expensive training and fine-tuning jobs from a single-site outage, backed by HITRUST-certified facilities at every site - audit-ready security, not just an internal policy document.
The distributed sites you already operate - central offices, regional hubs, edge PoPs - are a head start most GPU cloud providers don't have. WhiteFiber Continuum lets you turn that existing footprint into low-latency inference capacity close to your end users, on the same converged fabric that already carries your core traffic, instead of standing up a second, separately-managed network. As demand grows, that same architecture extends to additional edge locations without re-architecting what you've already built.
Your customers expect elastic scale and uptime SLAs; they don't expect to hear that you built the multi-site networking yourselves from scratch. WhiteFiber Continuum gives GPU cloud providers pooled, resilient capacity across two sites that can be resold as a single, unified pool, without the multi-site engineering effort falling on your own team. As demand grows, the same architecture extends to additional sites without a rebuild, so your infrastructure investment compounds instead of needing to be re-architected every time you scale
Last updated: May 2026
Lorem ipsum dolor sit amet, consectetur adipiscing elit. In luctus neque aliquam erat cursus, vitae tincidunt libero interdum. Nam non lacus sed lectus dapibus consectetur non et nulla. Praesent viverra dapibus lacus ut tincidunt.
Download for Free



Preferred Partner